在询问 ChatGPT 互联网上并不存在内容的时候,能给出较好答案(如用 ChatGPT 学建模);ChatGPT 能通过信 息猜你心中的想法;你可以制定一个全新的游戏规则让 ChatGPT 和你玩,ChatGPT 可以理解。
5.大模型生成时的参数怎么设置?
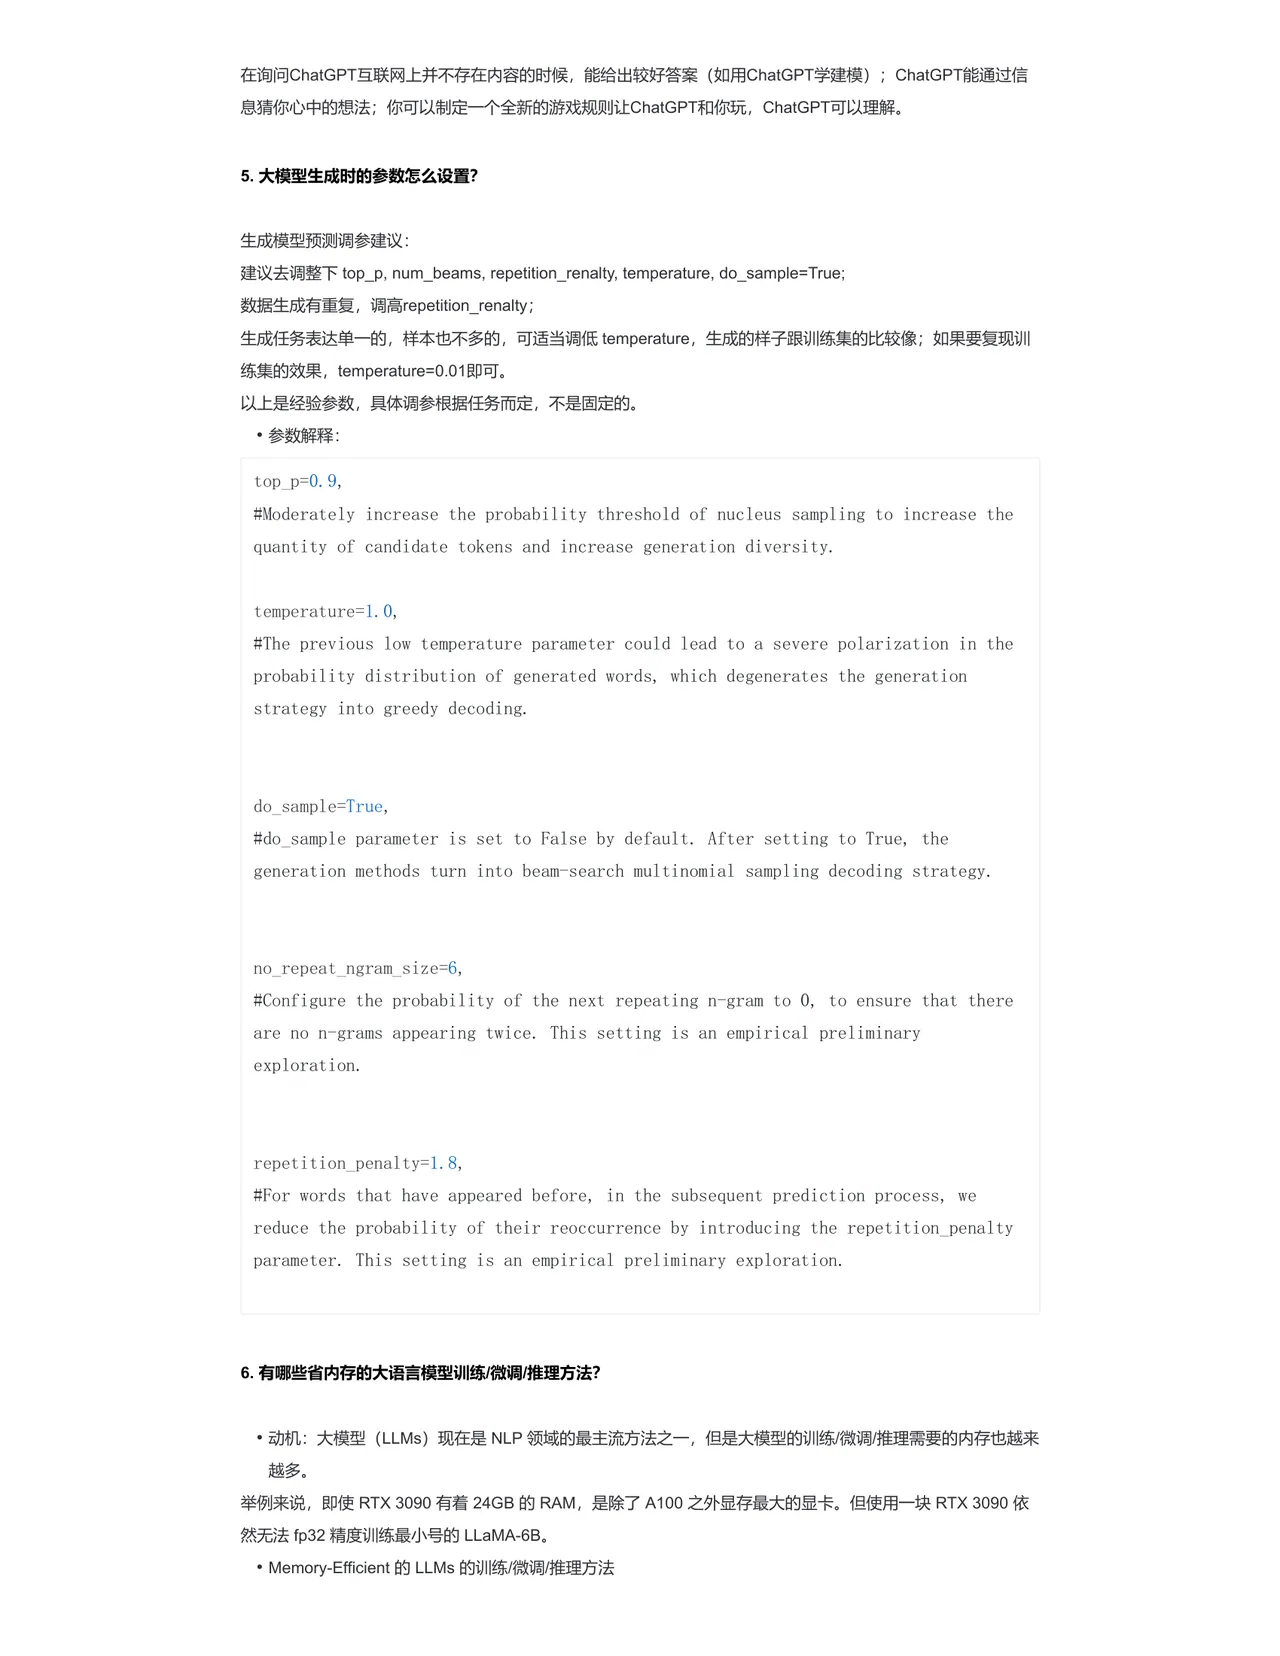
生成模型预测调参建议: 建议去调整下 top_p, num_beams, repetition_renalty, temperature, do_sample=True; 数据生成有重复,调高 repetition_renalty; 生成任务表达单一的,样本也不多的,可适当调低 temperature,生成的样子跟训练集的比较像;如果要复现训 练集的效果,temperature=0.01 即可。 以上是经验参数,具体调参根据任务而定,不是固定的。 •参数解释:
#Moderately increase the probability threshold of nucleus sampling to increase the quantity of candidate tokens and increase generation diversity.
temperature=l.0, #The previous low temperature parameter could lead to a severe polarization in the probability distribution of generated words, which degenerates the generation strategy into greedy decoding.
do_sample=True, #do_sample parameter is set to False by default. After setting to True, the generation methods turn into beam-search multinomial sampling decoding strategy.
no_repeat_ngram_size=6, #Configure the probability of the next repeating n-gram to 0, to ensure that there are no n-grams appearing twice. This setting is an empirical preliminary exploration.
repetition_penalty=1.8, #For words that have appeared before, in the subsequent prediction process, we reduce the probability of their reoccurrence by introducing the repetition penalty parameter. This setting is an empirical preliminary exploration.
6.有哪些省内存的大语言模型训练/微调/推理方法?
- 动机:大模型(LLMs)现在是 NLP 领域的最主流方法之一,但是大模型的训练/微调/推理需要的内存也越来 越多。 举例来说,即使 RTX 3090 有着 24GB 的 RAM,是除了 A100 之外显存最大的显卡。但使用一块 RTX 3090 依 然无法 fp32 精度训练最小号的 LLaMA-6B。
- Memory-Efficient 的 LLMs 的训练/微调/推理方法