训练、微调与数据面试题图文讲义763 字

大模型生成SFT数据方法面试题

·全库 121 / 611

《大模型生成SFT数据方法面试题》共 3 页、0.1 万字,通篇围绕 SFT、标注、数据集、微调 展开,归在「训练、微调与数据」这一层。

覆盖SFT标注数据集微调预训练成本

适合要自己训模型、或者判断这一版该不该训的人

目录骨架(6 节)
  1. 一、SFT 数据集如何生成?
  2. Backtranslation 篇
  3. 二、Self-Instruct 篇
  4. 3.1 什么是 Backtranslation?
  5. WizardLLM
  6. Alpaca GPT-4

原 PDF 已逐页还原成图,共 3 页,这里先放前 3 页,其中 2 页识别出了标题。右侧文字由 OCR 按版面重排,可能有个别错字,以图为准;点图可全屏放大。

本讲义目录 · 3 页
  1. 01一、SFT 数据集如何生成?
  2. 02Backtranslation 篇
  3. 03第 3 页
011 / 3
第 1 页:一、SFT 数据集如何生成?
第 1 页

一、SFT 数据集如何生成?

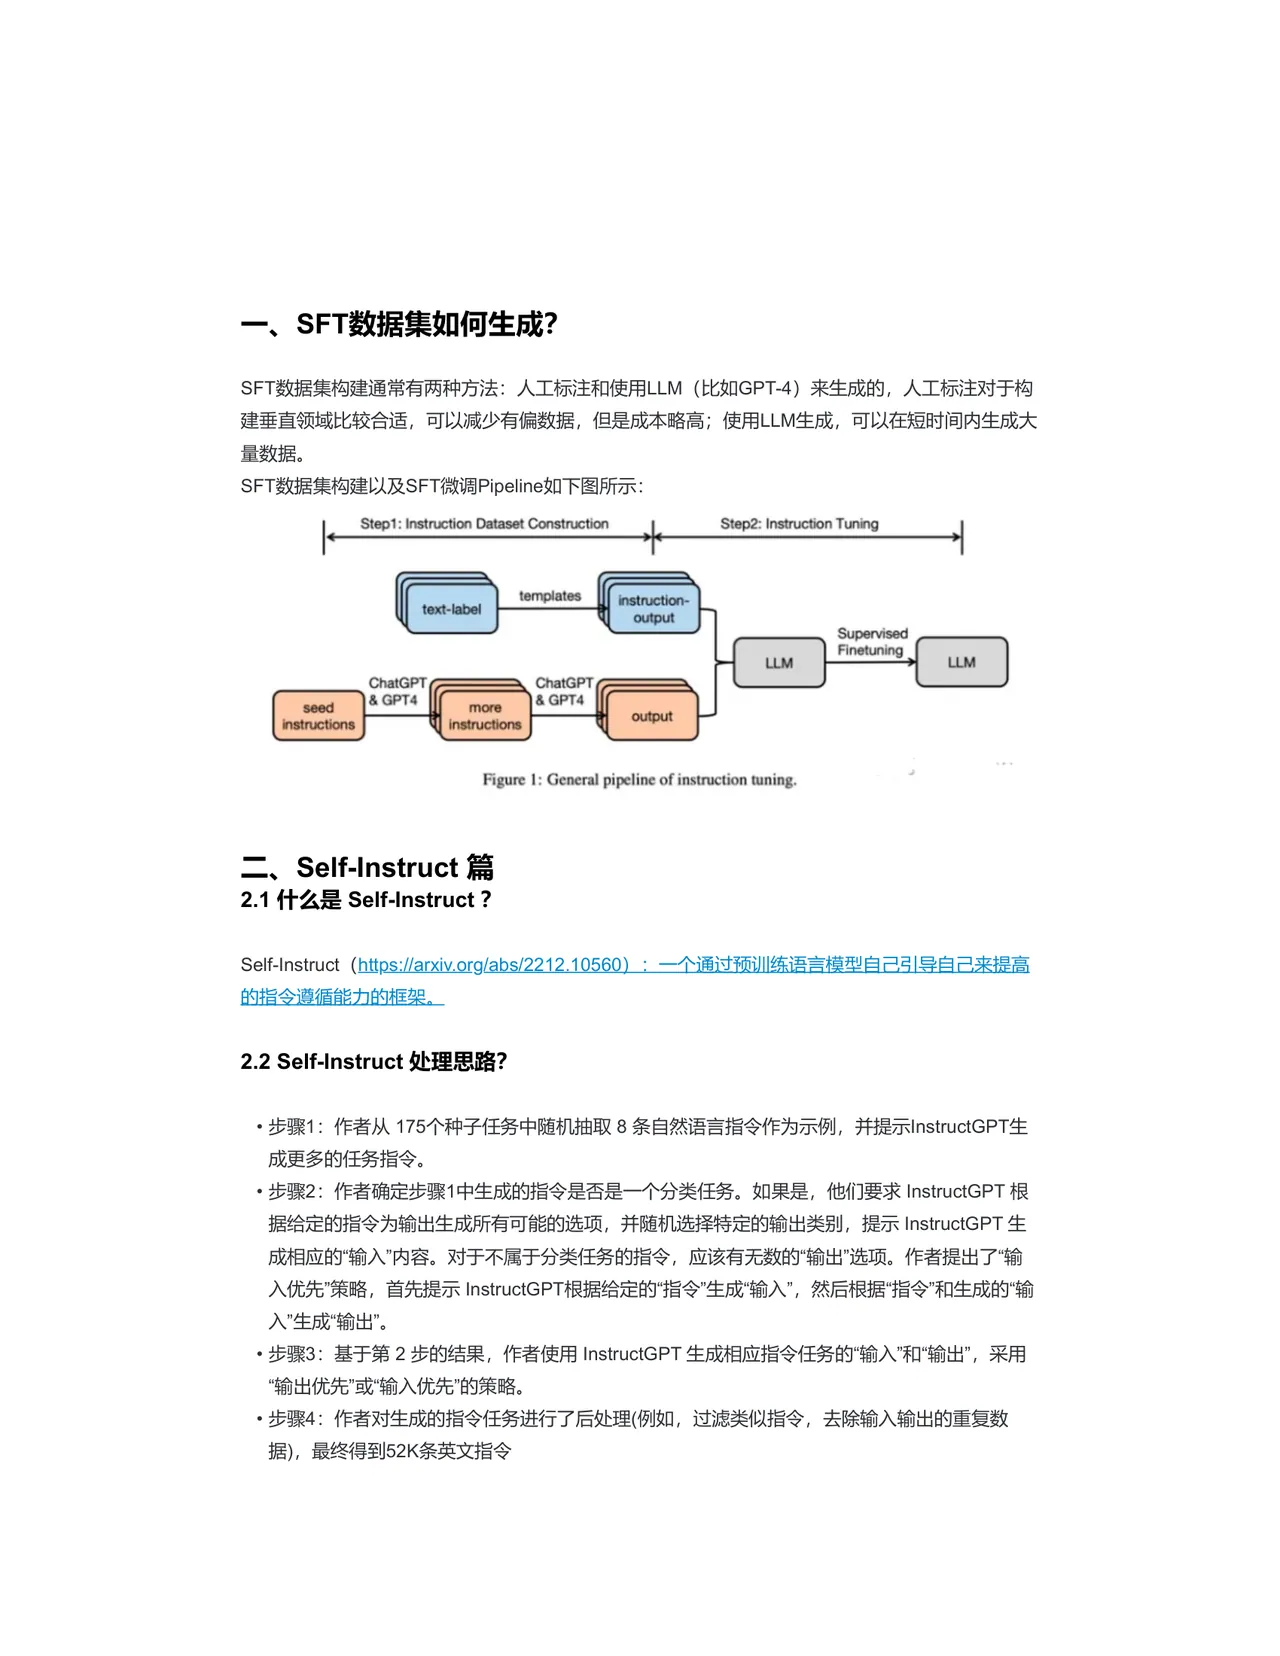
SFT 数据集构建通常有两种方法:人工标注和使用 LLM (比如 GPT-4)来生成的,人工标注对于构 建垂直领域比较合适,可以減少有偏数据,但是成本略高;使用 LLM 生成,可以在短时间内生成大 量数据。 SFT 数据集构建以及 SFT 微调 Pipeline 如下图所示:

Step1: Instruction Dataset Construction Step2: Instruction Tuning

templates instruction- output

Supervised Finetuning LLM LLM ChatGPT ChatGPT & GPT4 output instructions instructions

Figure 1: General pipeline of instruction tuning.

二、Self-Instruct 篇

2.1 什么是 Self-Instruct?

Self-Instruct (https://arxiv.org/abs/2212.10560):一个通过预训练语言模型自己引导自己来提高 的指令遵循能力的框架。

2.2 Self-lnstruct 处理思路?

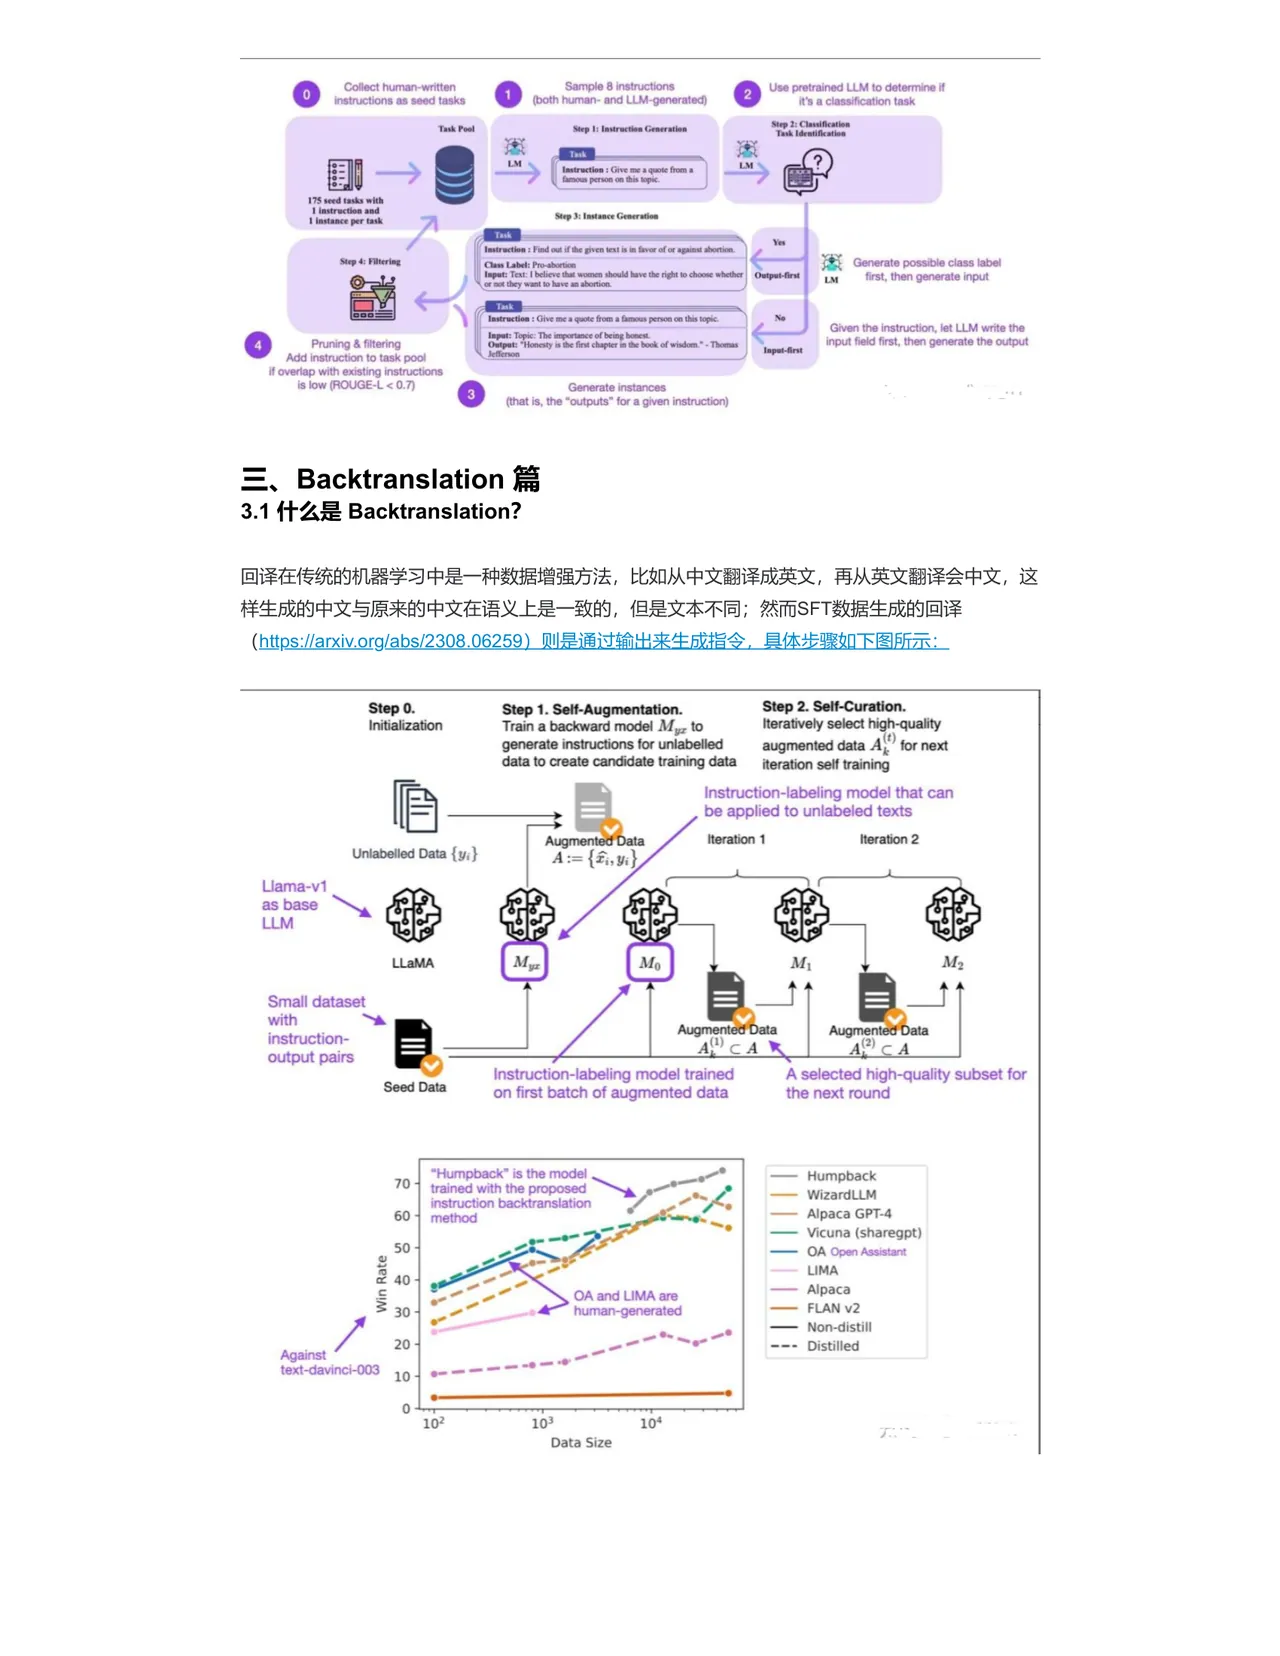
  • 步骤 1:作者从 175 个种子任务中随机抽取 8 条自然语言指令作为示例,并提示 InstructGPT 生 成更多的任务指令。
  • 步骤 2:作者确定步骤 1 中生成的指令是否是一个分类任务。如果是,他们要求 InstructGPT 根 据给定的指令为输出生成所有可能的选项,并随机选择特定的输出类别,提示 InstructGPT 生 成相应的“输入”内容。对于不属于分类任务的指令,应该有无数的“输出”选项。作者提出了“输 入优先”策略,首先提示 InstructGPT 根据给定的“指令"生成“输入”,然后根据“指令”和生成的“输 入"生成“输出”。
  • 步骤 3:基于第 2 步的结果,作者使用 InstructGPT 生成相应指令任务的“输入”和“输出”,采用 “输出优先”或“输入优先”的策略。
  • 步骤 4:作者对生成的指令任务进行了后处理(例如,过滤类似指令,去除输入输出的重复数 据),最终得到 52K 条英文指令
022 / 3
第 2 页:Backtranslation 篇
第 2 页

Backtranslation 篇

Sample 8 instructions Collect human-written Use pretrained LLM to determine if| (both human- and LLM-generated) it's a classification task

Instruction : Find out if the given text is in favor of or apainst aboet

Generate possible class label first, then generate input

Given the instruction, let LLM write the input field first, then generate the output Pruning & fitering Add instruction to task pool| if overlap with existing instructions Generate instances (that is, the "outputs" for a given instruction)

3.1 什么是 Backtranslation?

回译在传统的机器学习中是一种数据增强方法,比如从中文翻译成英文,再从英文翻译会中文,这 样生成的中文与原来的中文在语义上是一致的,但是文本不同;然而 SFT 数据生成的回译 (https://arxiv.org/abs/2308.06259)则是通过输出来生成指令,具体步骤如下图所示:

Step 2. Self-Curation. Step 1. Self-Augmentation. Initialization Iteratively select high-quality generate instructions for unlabelled data to create candidate training data iteration self training Instruction-labeling model that can be applied to unlabeled texts Iteration Iteration Augmented Data Unlabelled Data { yi } Llama-v1| LLM

Mo M2

LLaMA Small dataset with Augmented Data Augmented Data instruction- CA output pairs A selected high-quality subset for

Instruction-labeling model trained

on first batch of augmented data

Seed Data the next round

“Humpback" is the model Humpback

WizardLLM

trained with the proposed instruction backtranslation

Alpaca GPT-4

60- method Vicuna (sharegpt) - OA Open Assistant LIMA Alpaca human-generated Against text-davinci-003 10-

Data Size

033 / 3
第 3 页
第 3 页

(这一页没有可识别的文字)

这一页的文字很少,内容都在图里 —— 点开图片看大图更清楚。

资料里没有你的场景?

把你手上的数据和想解决的那个环节发上来,我们按具体情况回,不复述方法论。

发布需求