
训练、微调与数据面试题5036 字
预训练模型面试题
·全库 174 / 611
《预训练模型面试题》共 0.5 万字,通篇围绕 预训练、标注、微调、向量 展开,归在「训练、微调与数据」这一层。
覆盖预训练标注微调向量数据集场景
适合要自己训模型、或者判断这一版该不该训的人
目录骨架(8 节)
- 常见面试题
- 1 **预训练模型**
- 2 **序列自编码器和语言模型**
- 1.1 **迁移学习Transfer Learning**
- 1.2 **为什么要有预训练?**
- 1.3 **预训练模型用于下游任务的策略:固定特征提取器**
- 1.4 **预训练模型用于下游任务的策略:Fine-Tuning**
- 1.5 **为什么在NLP中迟迟没有出现类似CV预训练的范式?**
常见面试题
- 迁移学习Transfer Learning
- 为什么要有预训练?
- 预训练模型用于下游任务的策略:固定特征提取器
- 预训练模型用于下游任务的策略:Fine-Tuning
- 为什么在NLP中迟迟没有出现类似CV预训练的范式?
- 序列自编码器和语言模型
- 序列自编码器 Sequence Autoencoder
- 序列自编码受到了seq2seq的启发
- 序列自编码器的无监督特性
- 半监督预训练:利用有标注和无标注数据联合训练
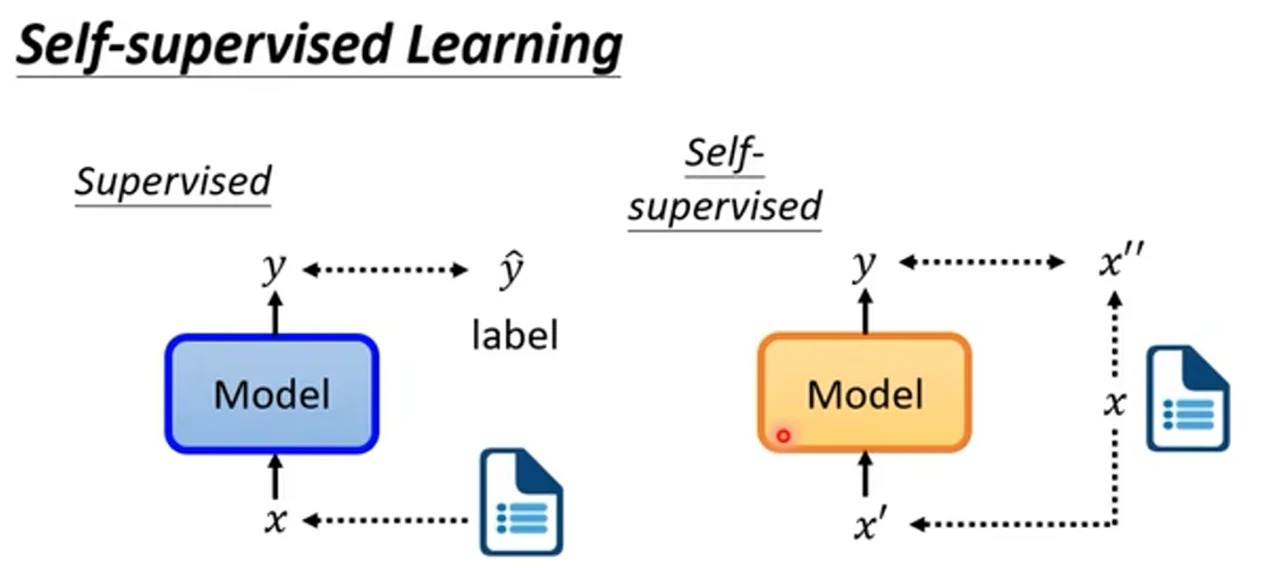
自监督学习*:对于样本x,自动生成一个输入x'和该输入理应对应的输出x''(往往是Ground Truth)。模型根据x'输出了y,而后y和Ground Truth x''做交叉熵损失函数,而后**反向传播**。*
在这一章中我们要介绍一篇很重要的论文。我们知道,GPT的全称是Generative Pretrained Transformer;2018,GPT和BERT的提出把NLP带入了预训练的时代。那么什么是预训练?什么是我们经常说的预训练+微调(Fine-tuning)的范式?在第8、第9章,我们会讲明白这些事。
用半监督学习/自监督学习去预训练一个语言模型是RNN时代NLP的一个非常天才的想法。具体论文参考:半监督学习(Semi-supervised Sequence Learning)。下面这段是文章的摘要:
| We present two approaches that use unlabeled data to improve sequence learning with recurrent networks. The first approach is to predict what comes next in a sequence, which is a conventional language model in natural language processing. The second approach is to use a sequenceautoencoder, which reads the input sequence into a vector and predicts the input sequence again. These two algorithms can be used as a "pretraining" step for a later supervised sequence learning algorithm. In other words, the parameters obtained from the unsupervised step can be used as a starting point for other supervised training models. In our experiments, we find that long short term memory recurrent networks after being pretrainedwith the two approaches are more stable and generalize better. With pretraining, we are able to train long short term memory recurrent networks up to a few hundred timesteps, thereby achieving strong performance in many text classification tasks, such as IMDB, DBpedia and 20 Newsgroups. |
|---|
#这篇论文的价值非常高,在那个Transformer模型还没有出现的2015年,RNN统治NLP的年代,它率先给出了基于无标签样本做自监督学习从而预训练一个RNN的范式。我认为它就是RNN时代的BERT和GPT。
1 预训练模型
#Note:预训练不一定是无监督的,但通常情况下预训练是指在大规模数据集上进行无监督的预训练。
1.1 迁移学习Transfer Learning
- 迁移学习(Transfer Learning)是一种机器学习技术,通过将在一个领域(源领域)中训练好的模型应用到另一个领域(目标领域)中,从而改善另一个领域的学习性能,加速在新领域中的学习过程。
- 在传统机器学习中,通常需要在目标领域中收集大量的数据并训练针对目标场景模型,但目标场景的标注数据可能是稀缺的。迁移学习利用了在源领域中学到的知识,通过从一个领域向另一个领域传递知识,可以解决在目标领域数据稀缺、标注困难或者模型难以收敛等问题。